Language-conditioned target acquisition 2026 · Preprint
EndoVLA-OOV
Language-Conditioned Out-of-View Target Acquisition in Robotic Endoscopy
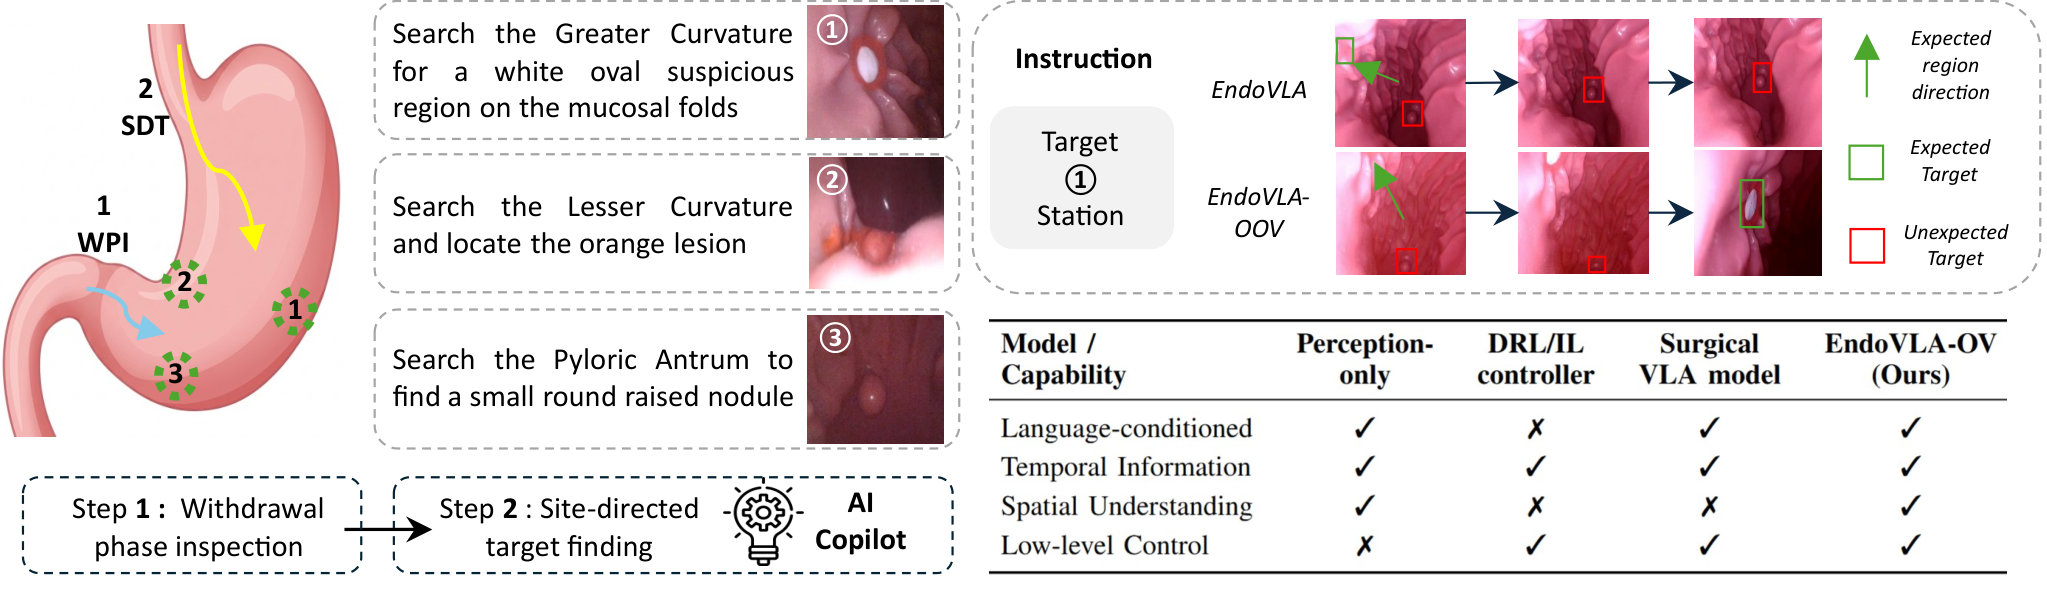
Finding a target starts before it enters the frame.
01 / The idea
Finding a target starts before it enters the frame.
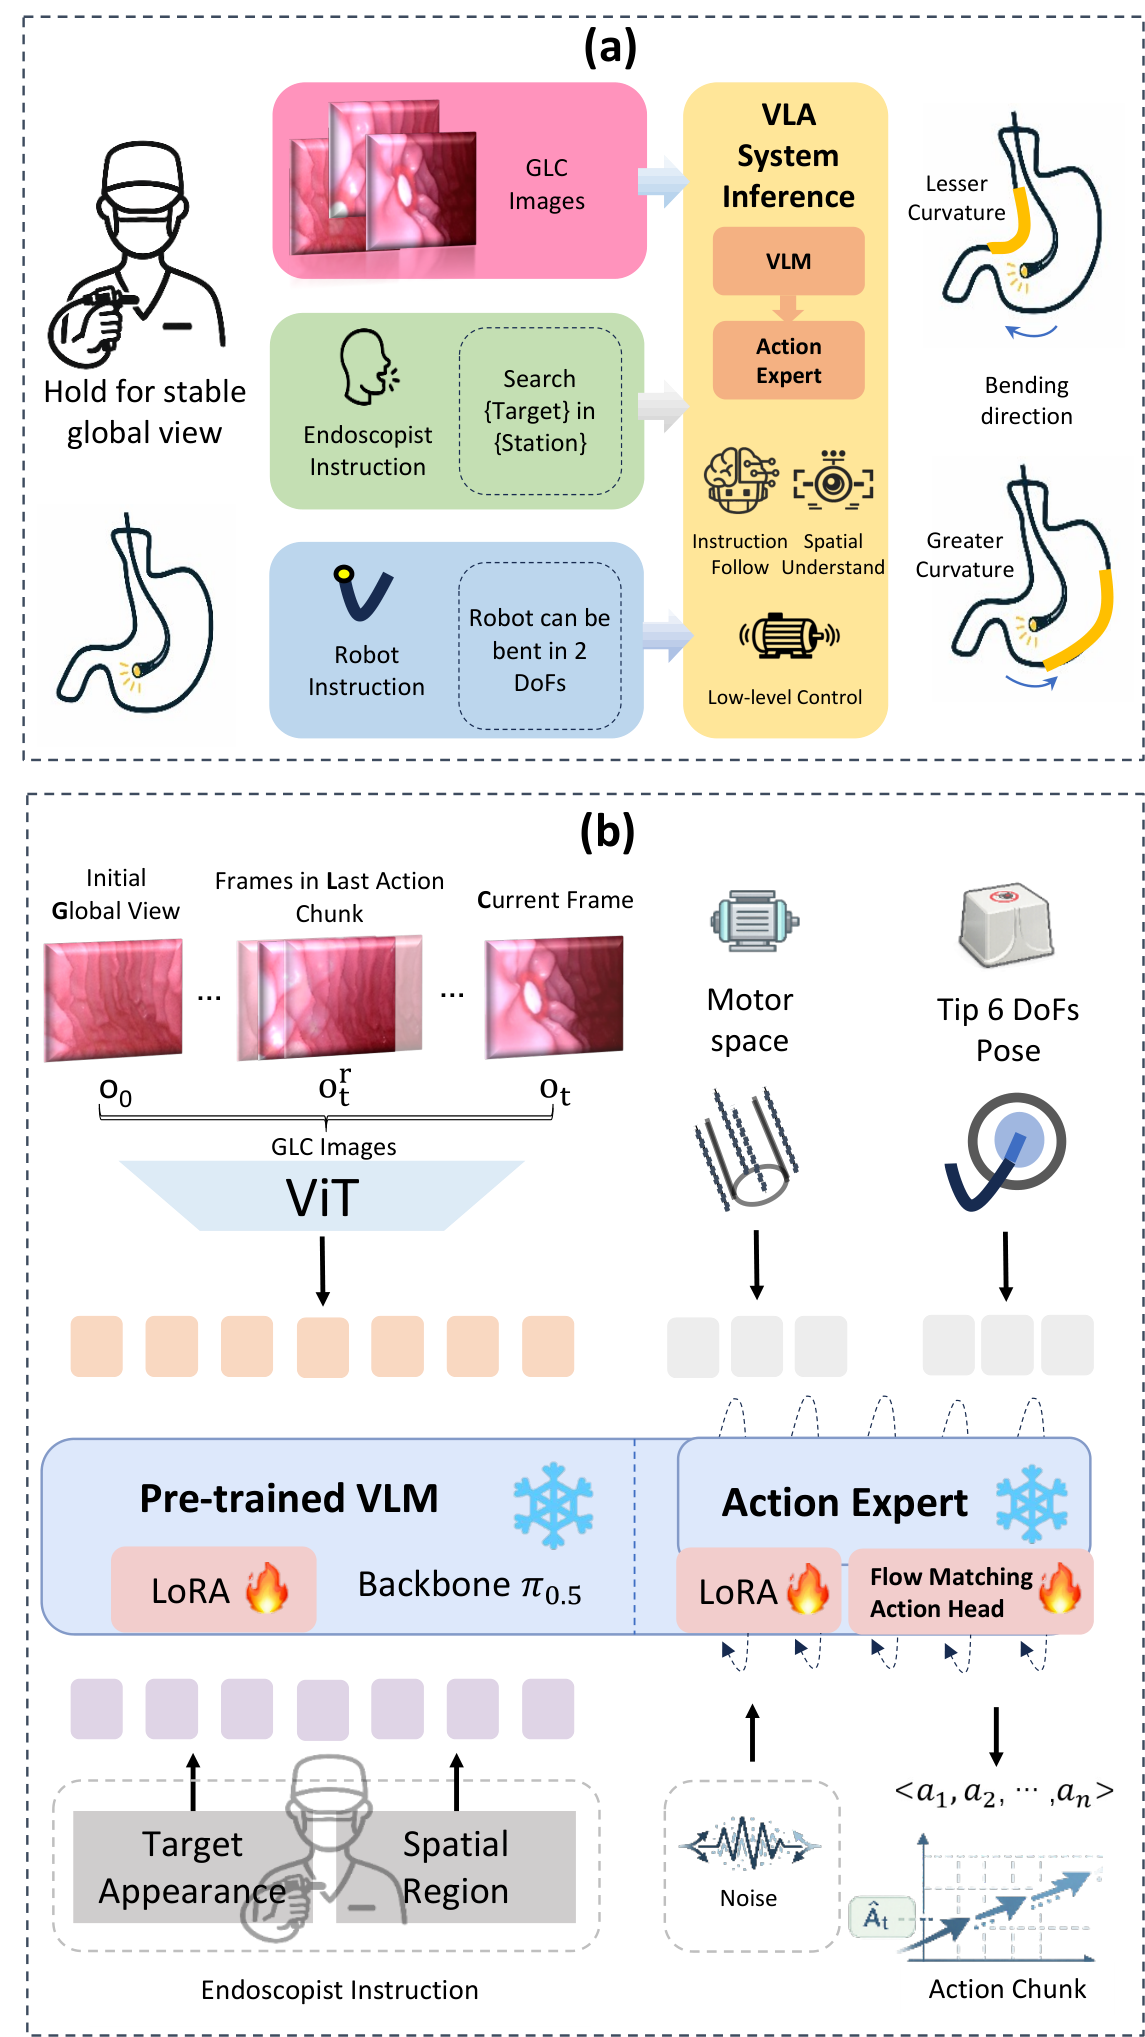
An instruction identifies the region to revisit. Initial, intermediate and current images help the policy search through partial observations, producing continuous commands for the two distal bending axes.
Acquisition result: full-data policy on a second robotic embodiment in an unseen ex-vivo environment. Acquisition and precise centering are evaluated separately. Evaluation details ↗
02 / The approach
How it works
From observations to a physical outcome.
Describe the target
Language specifies appearance and an anatomical region.
Use visual context
Earlier and current observations guide search beyond the present view.
Act continuously
The adapted policy predicts chunks of two-axis bending commands.
03 / In action
Watch the demonstration
Full demonstration of language-conditioned target acquisition and tracking.
04 / Reference
Build on this work
@misc{ng2026endovlaoov,
  title = {EndoVLA-OOV: Language-Conditioned Out-of-View Target Acquisition in Robotic Endoscopy},
  author = {Chi Kit Ng and Yidong Zhang and Tianchun Wu and Zhiqing Tang and Hanlin Zhao and Siu Hing Lui and Tao Yang and Jingsong Lin and Huxin Gao and Yeung Trevor and Raymond Tang and Hongliang Ren},
  year = {2026},
  eprint = {2610.24747},
  archivePrefix = {arXiv},
  primaryClass = {cs.RO},
  url = {https://arxiv.org/abs/2610.24747}
}